Software developer · Lomé & remote
Service 02 — Infrastructure & production deployment
Ship to production without losing your nights
Every release is an event, nobody really knows what's running in production, and incidents reach you through your users. I build the chain that carries your code from the repository to production, and the monitoring that warns you first.
- Docker · Kubernetes
- GitLab CI · GitHub Actions · ArgoCD
- Prometheus · Grafana · Loki · Tempo
- GitOps
- what is versioned in Git is what runs in production
- 0
- manual releases: everything goes through the pipeline
- 100%
- of the infrastructure described in a repository you own
They trusted me

Your challenges
Does your production rest on one person?
- 01
Releases are frightening
Shipping takes an evening, is done by hand, and nobody wants to be the one pressing the button.
- 02
Environments have drifted
It works locally, not on staging. Every server was configured by hand, at a date nobody remembers.
- 03
Your users tell you first
You learn about incidents by phone. No metrics, no centralised logs, no alerting.
- 04
A single expert
One person knows how production was built, and the infrastructure is written down nowhere.
Scope
What I put in place
Containerisation & environments
Clean images and identical environments from the developer's machine to production. No more "it worked on mine".
Integration & deployment pipeline
Tests, static analysis, build and deployment, all automated. Every approved change goes to staging, every tagged version to production.
Kubernetes & GitOps deployment
The declarative state in Git is the source of truth: ArgoCD reconciles the cluster with the repository. What runs is exactly what is versioned, and a rollback is a commit.
Observability & alerting
Centralised metrics, logs and traces, readable dashboards and alerts that wake the right person — on a threshold that actually means something.
Method
How an infrastructure engagement runs
Step 1 · 2 to 4 days
Assessment
How your application is deployed today, what is automated, what is not, and what rests on a single person. I come out of it with a target and a priority order.
Step 2 · 1 week
Containerisation & staging
Images, environment variables, secrets, and a staging environment that resembles production. Everything else builds on this.
Step 3 · 1 to 2 weeks
Pipeline & deployment
Continuous integration, automated deployment, and a rollback procedure tested for real — not merely written down.
Step 4 · 1 week
Monitoring & handover
Dashboards, calibrated alerts and an operations guide, then handover to your team so they run it without me.
What you get
Infrastructure your team can take over
A versioned infrastructure repository
Manifests, variables and encrypted secrets: the state of your platform is readable in Git, not in someone's memory.
Aligned environments
Development, staging and production configured the same way, with only the differences that must exist.
Dashboards and alerts
Grafana wired to your application and system metrics, with alert thresholds calibrated on what actually hurts you.
An operations guide
What to do when things break: restart, restore and rollback procedures, written to be followed under stress.
Why work with me
Three commitments I keep on every engagement
- 01
You talk to the person writing the code
No salesperson, no middleman, no junior swapped onto your project after signature. Whoever scopes the work is whoever delivers it.
- 02
You stay the owner
Code, infrastructure, accounts, documentation: everything sits with you. You can change provider without starting over.
- 03
I say no when I should
If an off-the-shelf tool or three days of advice solves your problem better than custom development, I'll tell you — even when it costs me the engagement.
In practice
An example: MTN Benin and the BCEAO switch
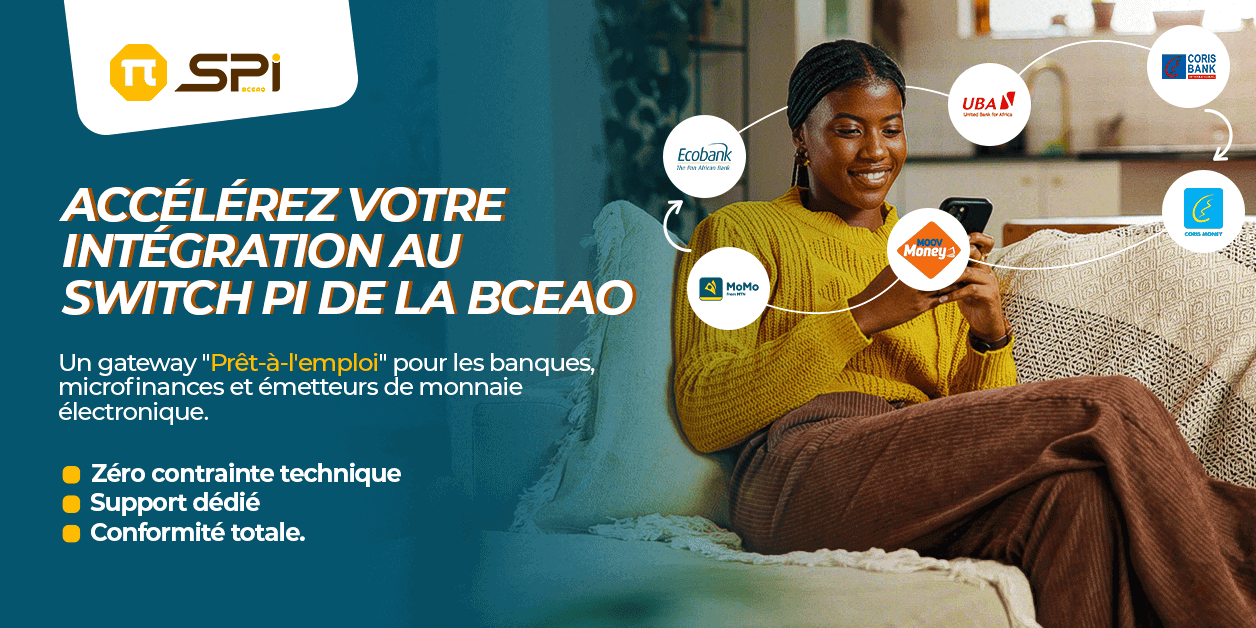
On MTN Benin's integration with the BCEAO Instant Payment System, I designed the Kubernetes deployment chain with GitOps and ArgoCD, along with end-to-end observability — metrics, logs and traces, from the incoming request to the Interoperability Platform's response.
View the project →Frequently asked
What people ask before we start
Do we have to move to Kubernetes?
No, and it is often a bad idea. A single application running on two servers gains nothing from it: Docker, a pipeline and decent monitoring are enough. I propose Kubernetes when load, the number of services or availability requirements justify it.
Do you work with our current hosting?
Yes. Dedicated server, VPS or cloud provider: I work with what you already have. If a change is worth making, I'll cost it and you decide.
What happens after the engagement?
Everything sits in your repository, with an operations guide. I can stay available for occasional support in the first weeks, but the goal is for your team to run it alone.
How long does a setup take?
Count 3 to 6 weeks for a complete chain — containerisation, pipeline, deployment and monitoring — on an existing mid-sized application.
Describe your current deployment chain
I'll answer within 48 hours with the two or three things I would fix first, and why.
Get in touch